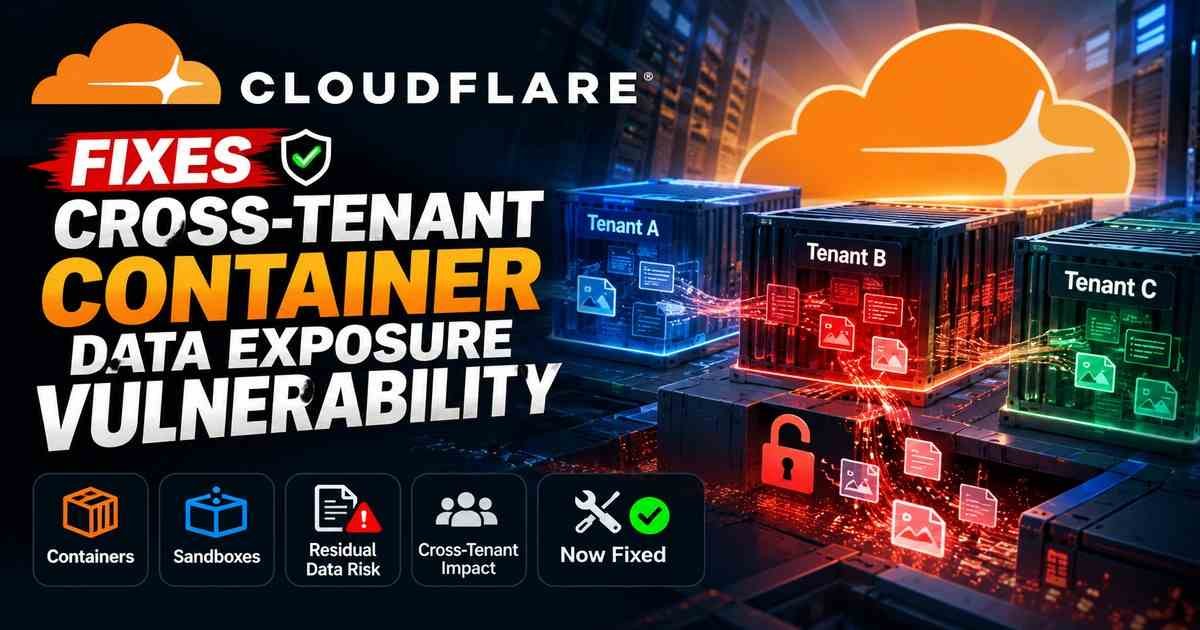
Cloudflare has fixed a cross-tenant data exposure flaw in Cloudflare Containers that could allow one paying customer to recover residual disk data previously used by another customer’s container on the same underlying host. The issue also affected Cloudflare Sandboxes, which is built on Containers.
The flaw was responsibly reported on September 4, 2026 by Oren Yomtov of Accomplish through Cloudflare’s bug bounty program. Cloudflare says it fully remediated the issue across the Containers fleet, requires no customer-side configuration changes, and found no evidence of malicious exploitation in the historical disk-I/O telemetry it retained.
Cloudflare Container Data Exposure Vulnerability: What Happened?
Cloudflare Containers runs customer workloads on multi-tenant infrastructure. Each container gets a writable root disk backed by Linux device-mapper thin provisioning, or dm-thin. When a container is deleted, its physical storage blocks are returned to a shared pool and can later be reused by a different customer workload scheduled on the same host.
The affected storage pools used a 64 KiB thin-block size and were configured with the skip_block_zeroing option. That setting prevented reused physical blocks from being cleared before being reassigned.
As a result, when a new container wrote only part of a reused block, the remainder of that 64 KiB block could still contain bytes from the previous tenant’s container.
How the Cross-Tenant Data Leak Worked
Reading an unmapped region of a fresh thin disk did not directly expose previous data. Instead, Cloudflare says the researchers triggered block allocation by writing one aligned 4 KiB block into selected 64 KiB regions that corresponded to free space in the guest’s ext4 filesystem.
That 4 KiB write caused dm-thin to allocate a physical 64 KiB block from the shared storage pool. Because zeroing was disabled, only the 4 KiB written by the new container was replaced. The remaining 60 KiB could retain residual data from the block’s previous owner.
A subsequent raw-device read from /dev/vdc could then expose bytes the new container itself had never written.
What Researchers Recovered
Cloudflare says the researchers observed residual material on 18 of 24 production placements and 20 of 22 underlying nodes across four continents. The recovered block types included directory structures, database pages and structurally complete SQLite databases.
Importantly, the researchers’ submitted materials did not include third-party filenames, identifiers, credentials, hostnames, addresses or recovered content values. They reported aggregate counts and format checks, and later confirmed that any recovered data under their control was securely deleted after disclosure.
What an Attacker Could and Could Not Do
| Potential capability | Limitation |
|---|---|
| Recover residual data from storage blocks previously used by another tenant. | Could not choose a specific customer, workload, host or data set. |
| Potentially expose filesystem metadata, directory structures, database pages or application data. | Residual data was not guaranteed to be present. |
| Cross the tenant-isolation boundary at the storage layer. | Researchers did not demonstrate modification of another customer’s active disk. |
| Read data from reused blocks after controlled writes. | Could not access a currently attached disk belonging to another active workload. |
Why Cloudflare Sandboxes Were Also Affected
Cloudflare Sandboxes is built on top of Cloudflare Containers, so it inherited the same storage behavior. This matters because Sandboxes is designed to run untrusted or dynamically generated code, including AI-agent workloads.
The vulnerability therefore was not limited to ordinary containerized applications. Any workload using the affected container storage stack could potentially have encountered reused blocks containing residual data from a previous tenant.
Cloudflare’s Two-Step Remediation
1. Re-enable block zeroing
Cloudflare’s first mitigation removed skip_block_zeroing from the dm-thin pool configuration. This restored the default behavior of clearing newly allocated blocks before exposing them to a container.
The researchers independently confirmed that their proof of concept stopped working after this change.
2. Retire existing mappings and cached snapshots
Turning zeroing back on was not enough by itself, because blocks already mapped into running container disks or cached image layers could still retain old data.
Cloudflare therefore drained hosts, restarted virtual machines, retired running container disks and cleared cached image snapshots created before the mitigation. Cloudflare says this cleanup was completed across the affected fleet on September 19.
Remediation Timeline
| Date | Event |
|---|---|
| September 4, 15:26 UTC | Oren Yomtov of Accomplish reported the issue through HackerOne. |
| September 4, 18:45 UTC | Cloudflare opened a security incident and confirmed the production configuration involved. |
| September 4, 21:27 UTC | Cloudflare merged the runtime fix and reuse test. |
| September 4, 23:15 UTC | Fleet rollout began. |
| September 7, 06:13 UTC | Rollout completed and cleanup of old pool data began. |
| September 14 | Researchers confirmed the proof of concept no longer worked. |
| September 19, 15:03 UTC | Cloudflare completed cleanup of pre-mitigation cached snapshots across the affected fleet. |
| September 24 | Cloudflare publicly disclosed the vulnerability and response. |
Did Cloudflare Find Evidence of Exploitation?
Cloudflare says it reviewed retained historical disk-I/O telemetry using signatures based on the researchers’ proof of concept and Cloudflare’s own internal reproduction.
The company says the only activity matching the technique came from the researchers and Cloudflare engineers conducting authorized validation. Cloudflare found no additional activity consistent with malicious exploitation of this specific method.
That conclusion should be read precisely: it means Cloudflare found no evidence in the historical telemetry it retained. It does not establish that the vulnerable configuration had never existed before the retained telemetry window.
Do Customers Need to Take Action?
Cloudflare says no customer-side configuration changes are required. The remediation was applied at the infrastructure layer across the Containers fleet.
Customers using Containers or Sandboxes may still want to review application logs, secret exposure assumptions and incident-response procedures as a precaution, particularly if sensitive material was written to ephemeral container filesystems.
Why This Matters for Multi-Tenant Container Security
The incident highlights a broader cloud-security principle: tenant isolation depends on more than CPU, memory and process boundaries. Storage lifecycle behavior matters too.
- Reused storage must be sanitized before reassignment. Residual data can remain even when a workload itself is correctly destroyed.
- Cache layers need the same isolation guarantees as active disks. Cloudflare’s second remediation step was necessary because old cached snapshots could preserve pre-fix mappings.
- Multi-tenant systems need lifecycle-aware security testing. Creating, deleting and reallocating workloads can reveal issues that ordinary single-instance testing misses.
- Telemetry matters for incident response. Without historical I/O data, validating whether a storage-layer technique was abused becomes much harder.
The same least-privilege and isolation principles apply across broader cloud-native security. Our DevSecOps security guide covers container security, IAM and software supply-chain controls, while our Terraform state drift guide explains how unmanaged infrastructure changes can introduce operational risk.
What the Research Does — and Does Not — Prove
| Supported by Cloudflare’s disclosure | Not established |
|---|---|
| Residual data from previous tenants could be recovered from reused storage blocks. | That a specific customer was deliberately targeted. |
| The issue affected Cloudflare Containers and Cloudflare Sandboxes. | That every container placement contained recoverable third-party data. |
The underlying cause involved skip_block_zeroing on shared dm-thin pools. | That attackers could modify another customer’s active workload. |
| Cloudflare remediated the issue fleet-wide and found no evidence of malicious exploitation in retained telemetry. | That malicious exploitation can be ruled out outside the telemetry Cloudflare retained. |
Bottom Line
The Cloudflare container data exposure vulnerability was a storage-isolation flaw, not a traditional container escape. A customer could potentially recover residual data from previously used disk blocks after those blocks were reassigned on the same underlying host.
Cloudflare fixed the issue by restoring block zeroing and then cleaning up pre-existing mappings and cached snapshots across the fleet. The company says customers do not need to make configuration changes and that it found no evidence of malicious exploitation.
