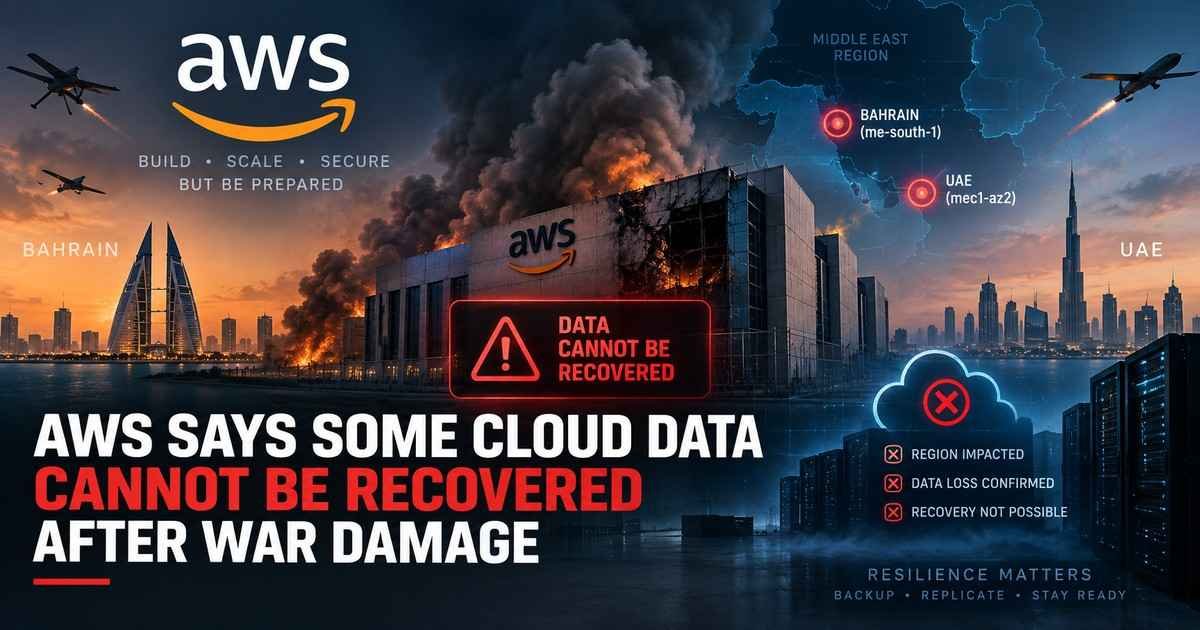
AWS cloud data loss in Bahrain and the UAE has become a major resilience issue after Amazon Web Services said it could not restore access to some resources and data hosted exclusively in war-damaged infrastructure.
In a September 15, 2026 service-health update, AWS said resources and data hosted exclusively in the Middle East (Bahrain) Region, me-south-1, could not be restored after damage affected multiple Availability Zones. In the Middle East (UAE) Region, me-central-1, AWS said it could not restore resources and data hosted exclusively in mec1-az2, while recovery work continued for regional services and the other affected UAE zones.
The incident is an unusual example of a cloud resilience failure caused by large-scale physical damage rather than a routine software, networking, or power outage. It also demonstrates an important architecture lesson: Multi-AZ deployment and Multi-Region disaster recovery solve different failure scenarios.
What AWS Has Confirmed
AWS’s public health update says the damage in Bahrain affected multiple Availability Zones and exceeded what its regional and Multi-AZ services were designed to withstand. After assessing the affected infrastructure, AWS concluded that it could not restore access to resources and data that had remained exclusively inside the Bahrain Region.
AWS had begun recommending that Bahrain customers move workloads to other Regions after the first Availability Zone was damaged in March. A later disruption in April made the Region unavailable. According to AWS, most customers were able to re-establish operations in other Regions, using backups where available or alternative recovery approaches.
In the UAE, the situation is narrower. AWS says mec1-az2 remains unrecoverable for resources and data that existed only in that zone. AWS continues working on regional recovery and on resources associated with mec1-az1 and mec1-az3.
AWS documentation lists three Availability Zones in the UAE Region: mec1-az1, mec1-az2, and mec1-az3. The Bahrain Region similarly consists of three Availability Zones. Availability Zones are designed as physically separate infrastructure locations within a Region, but they still belong to the same regional fault domain.
What Happened to the AWS Facilities?
Reuters reported that AWS facilities in Bahrain and the UAE were damaged during missile and drone strikes connected to the 2026 conflict involving Iran, Israel, and the United States. AWS’s public service-health updates focus on the infrastructure impact and recovery status rather than providing a detailed military assessment.
For cloud customers, the operational consequence is more important than the geopolitical attribution: some resources that existed only inside the affected infrastructure can no longer be accessed through AWS recovery efforts.
That distinction matters. The safest description is not that every piece of customer data in Bahrain or the UAE was lost. Customers with backups, replicas, or copies in other Regions were able to recover workloads. The unrecoverable portion is the data and resources that were hosted exclusively in the affected footprint and had no accessible external copy.
Multi-AZ Is Not the Same as Multi-Region
AWS Regions are built from multiple Availability Zones. A Multi-AZ architecture is intended to keep applications available when one zone experiences a localized infrastructure failure.
That design is extremely useful for failures such as isolated power events, hardware problems, local networking failures, or other disruptions limited to a single Availability Zone. It is not the same as protection against a disaster large enough to affect several Availability Zones across the same Region.
AWS’s own disaster-recovery guidance recommends a Multi-Region strategy when the required failure boundary extends beyond a single Region. AWS describes Regions as strong fault-isolation boundaries and recommends cross-Region backup and recovery for large-scale disasters that could make a source Region unavailable.
The Bahrain incident is a practical example of that distinction. When damage spans enough of a Region, redundancy inside that same Region may no longer be sufficient.
The Shared Responsibility Lesson
AWS’s Well-Architected guidance describes resilience as a shared responsibility.
AWS is responsible for the resilience of the underlying cloud infrastructure. Customers, however, are responsible for designing workloads to meet their own availability and disaster-recovery requirements. That includes decisions around backups, replication, versioning, Recovery Point Objectives (RPO), and Recovery Time Objectives (RTO).
For data resilience specifically, AWS states that customers are responsible for backup, versioning, and replication strategies.
That does not make physical infrastructure failure a customer-caused event. It means organizations need to decide in advance what level of failure their architecture must survive and then build a recovery design that matches that requirement.
What Cloud Teams Should Review Now
Organizations using AWS should use this incident as a reason to test whether their disaster-recovery design actually survives a regional failure rather than only an Availability Zone failure.
- Identify single-Region data: Find databases, snapshots, object stores, volumes, state files, and application data that exist in only one Region.
- Review cross-Region backups: AWS Backup can copy supported backups to another Region, creating a recovery path if the source Region becomes unavailable.
- Validate RPO and RTO: A backup is useful only if its age and restore time meet the business requirement.
- Test restoration: Regular recovery exercises are necessary to verify that backups can actually recreate a working application stack.
- Protect infrastructure definitions: Infrastructure-as-Code templates should be available outside the failed Region so networking, compute, IAM, and application dependencies can be rebuilt elsewhere.
- Map hidden dependencies: DNS, secrets, container images, CI/CD systems, artifact repositories, identity providers, and third-party integrations can prevent a successful failover even when the primary database is backed up.
Infrastructure state deserves particular attention. A recovery plan that protects application data but loses critical deployment state or configuration can still lead to a slow and risky rebuild. TechUpdate24’s guide to Terraform state drift and infrastructure consistency explains why infrastructure state needs to be managed deliberately rather than treated as an afterthought.
Backups Should Cross the Same Failure Boundary You Are Planning For
Keeping backups in the same Region can protect against many common problems, including accidental deletion and some infrastructure failures. But a Regional disaster changes the fault boundary.
AWS’s disaster-recovery architecture guidance specifically describes copying backups to another Region as protection against the largest scope of disasters. If the primary Region cannot operate, those copies can be restored in a designated recovery Region.
For critical workloads, teams may also consider separate AWS accounts for recovery copies. Cross-account isolation can reduce the chance that a security incident or administrative mistake affecting the production account also destroys recovery assets.
The exact design depends on workload criticality, data-residency requirements, cost, and acceptable RPO/RTO. Not every application needs active-active Multi-Region infrastructure. Some may be adequately protected by tested cross-Region backup and restore, while mission-critical systems may require warm standby or active workloads in multiple Regions.
Why This Matters Beyond the Middle East
This incident does not mean AWS Availability Zones or Regions are generally unreliable. It demonstrates that every architecture has a defined failure boundary.
Multi-AZ designs are built to provide strong resilience against Availability Zone failures. Multi-Region designs extend that protection to events large enough to affect an entire Region. The more critical the workload, the more important it is to make that boundary explicit rather than assume the cloud provider automatically provides recovery across every possible scope of disaster.
The same principle applies to security incidents. Credentials, infrastructure definitions, backups, and recovery systems should not all depend on one shared failure domain. TechUpdate24 has previously covered how exposed AWS credentials can create broad cloud access risk; resilience planning should account for both physical failures and compromised identities.
Bottom Line
AWS says it has exhausted restoration options for resources and data hosted exclusively in the Bahrain Region and cannot restore data hosted only in the mec1-az2 Availability Zone in the UAE. Customers with backups or copies outside the affected footprint had a recovery path; data that existed only inside the damaged infrastructure may remain inaccessible.
For cloud architects, the main lesson is not simply to “use multiple Availability Zones.” It is to match the recovery architecture to the failure scenario the business actually needs to survive. If a Regional outage is inside your disaster model, backups and recovery capability must cross Regional boundaries too.
Official Sources
- AWS Health Dashboard
- AWS Well-Architected: Shared Responsibility Model for Resiliency
- AWS Availability Zones Reference
- AWS Disaster Recovery Architecture: Backup and Restore
